Loading service0%
We ensure a smooth, secure performance of your IT solutions.
With our managed IT services, you can lower risk, reduce downtime, and lighten your business's day-to-day workload. We monitor your systems and applications, manage security, maintain your databases, and provide support around the clock. By spotting and fixing problems early, we help you avoid disruptions and let your team focus on new ideas.
Within 90 days, you'll have a clear view of your infrastructure's health, well-defined service agreements, and a setup that takes day-to-day management off your team's plate.
A clear view of your infrastructure's health.
Well-defined service agreements that set expectations.
A setup that takes day-to-day management off your team's plate.
After launch, the development team moves on. This often leaves roles and responsibilities unclear, especially when issues arise after hours.
Without proper systems, problems often go unnoticed until something breaks. If monitoring and escalation are lacking, users can be affected before anyone is aware.
Your talented IT team is stretched thin, juggling product management, support, security, and maintenance, which can cause coverage gaps.
When your team is overloaded, they react rather than do things proactively. Delayed security patches, postponed performance fixes, and missed database maintenance can compound into bigger risks.
After launch, the development team moves on. This often leaves roles and responsibilities unclear, especially when issues arise after hours.
Your talented IT team is stretched thin, juggling product management, support, security, and maintenance, which can cause coverage gaps.
Without proper systems, problems often go unnoticed until something breaks. If monitoring and escalation are lacking, users can be affected before anyone is aware.
When your team is overloaded, they react rather than do things proactively. Delayed security patches, postponed performance fixes, and missed database maintenance can compound into bigger risks.
The result is a product that performs well in development, but underperforms in production. This underperformance is not due to initial design, but rather to insufficient post-launch oversight.
In more critical cases, security or compliance incidents may occur. These incidents could have been prevented, but were not flagged due to the absence of appropriate monitoring systems.
Properly managed IT services are nearly invisible. Infrastructure runs smoothly, applications perform, security stays current, and your team can build rather than firefight. The goal: prevent problems early. Four principles shape every managed infrastructure services engagement:
Waiting for failure isn't a strategy; it's costly. We monitor infrastructure, application performance, security, and database health to fix issues before users notice. Managed services prevent incidents; support merely responds.
Properly managed IT services are nearly invisible. Infrastructure runs smoothly, applications perform, security stays current, and your team can build rather than firefight. The goal: prevent problems early. Four principles shape every managed infrastructure services engagement:
We agree on response times, uptime, escalation steps, and how we'll communicate before we start as an IT managed service provider. This proactive service begins with clear standards and success measures.
NeXus helps your team do more by handling what's hard to manage on their own. Your team still has full visibility, control, and decision-making power, while we handle daily operations so they can focus on bigger priorities.
We keep records of every environment, architecture, dependency, setup, and decision. When things aren't documented, they depend on one person's memory. We make sure your infrastructure is clear, well-documented, and easy to hand over.
Every IT service project begins with a full audit of your infrastructure. We map out what's running, how it connects, what it relies on, and where the risks are. We only take responsibility for environments we fully understand.
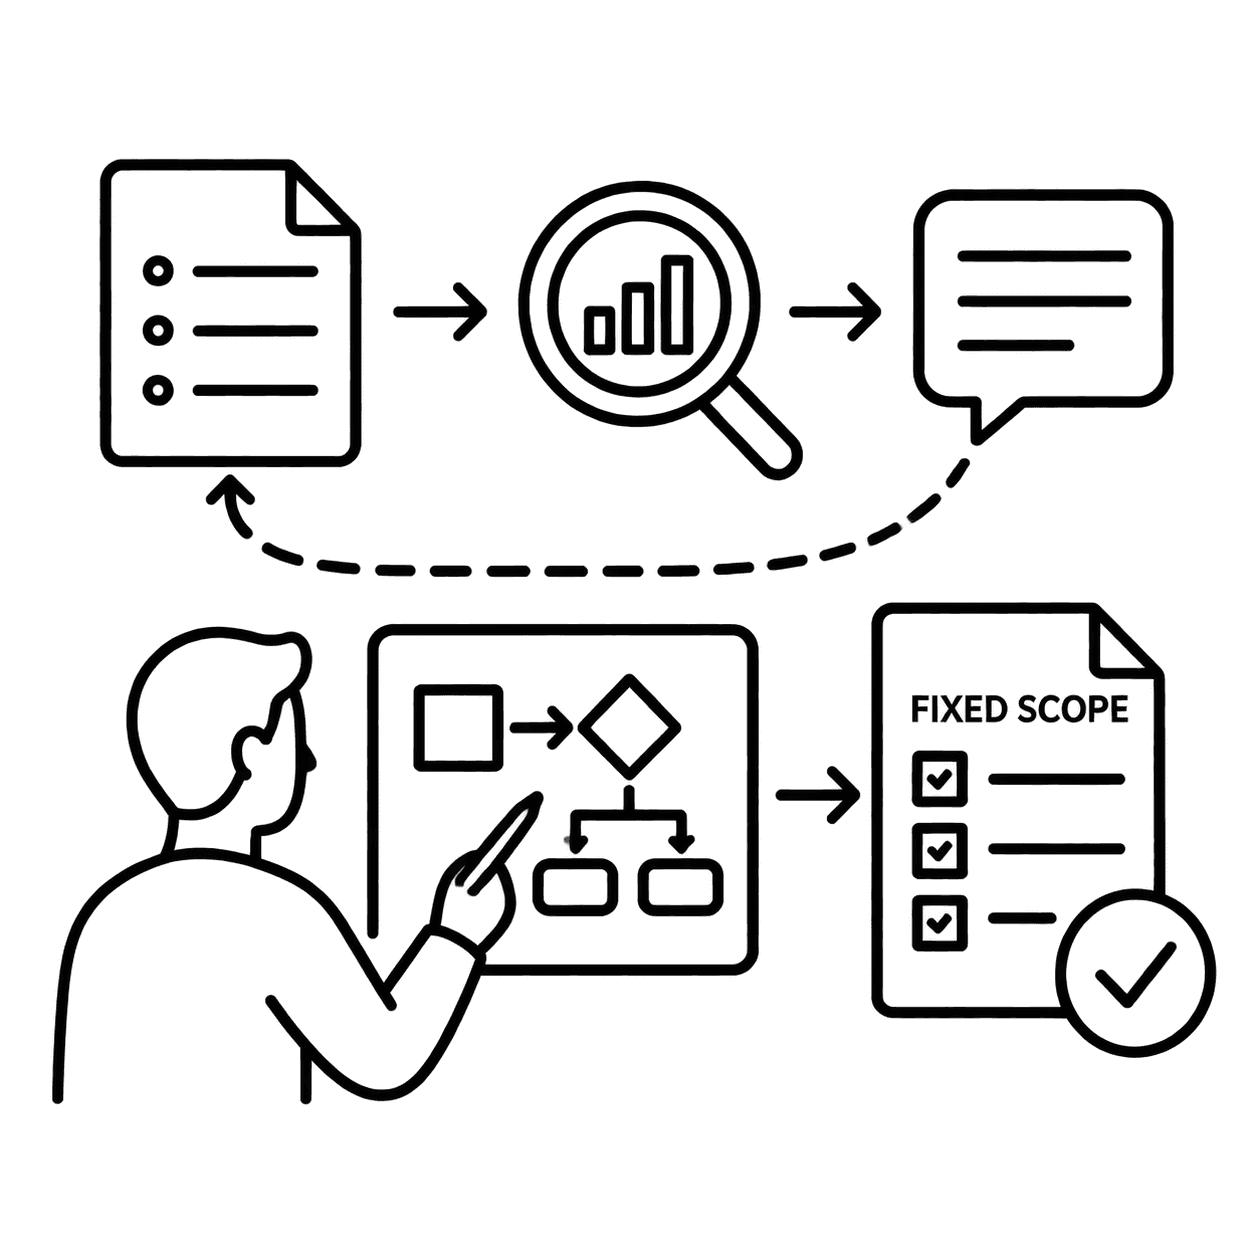
Too many alerts for minor issues can overwhelm your team, while insufficient monitoring can miss important problems. We tailor monitoring, escalation, and reporting to your environment and risk level, so your team only gets alerts that matter.
If deployment pipelines aren't managed, they can drift out of sync, build up technical debt, and become less secure. Our managed software services include DevOps oversight to keep your deployment systems up to date, stable, and easy to review, as well as your applications.
Dashboards, reporting cadences, and documented runbooks mean your internal team has full visibility into what we're managing and how. IT technology solutions managed as a black box create dependency. Ours creates transparency.
Every managed IT services engagement follows the same onboarding-to-operations sequence:
(Delivery Parameters of Managed IT Services from NeXus)
A complete map of the managed environment, architecture, dependencies, configuration decisions, and identified risk areas, produced at the start of every engagement and maintained throughout.
Operations run on undocumented infrastructure are fragile. When the person who set up the environment leaves, the knowledge leaves with them. Documentation is what makes the infrastructure transferable, auditable, and recoverable.
Your team understands what's running and why, enabling operational decisions to be made with full context, not partial knowledge.
Eliminates the single point of knowledge risk that makes undocumented environments vulnerable when key people are unavailable.
Documented service levels covering uptime commitments, incident response times by severity, escalation paths, communication protocols, and reporting cadences, agreed before operations begin.
IT operations management without defined service levels is a relationship without accountability. SLAs don't just protect the client; they give the operations team a clear standard to work to and a clear measure of whether they're meeting it.
Both teams know what good looks like, how it gets measured, and what happens when it isn't met, before the first incident tests the relationship.
Prevents ambiguity around response expectations that can turn minor incidents into major relationship problems.
A fully configured monitoring setup across infrastructure, application performance, database activity, security events, and pipeline status, with alerting thresholds calibrated to the environment and escalation paths connected to the SLA framework.
Issues that aren't monitored aren't managed; they're discovered after they've already caused impact. Monitoring configured to the specific environment surfaces the signals that matter without producing the noise that gets ignored.
Problems are caught at the monitoring layer before they reach users, cause data exposure, or require emergency recovery.
Reduces mean time to detection on infrastructure, security, and performance issues from hours to minutes.
Documented procedures for every routine and incident scenario the managed environment requires, maintenance tasks, deployment processes, incident response, escalation flows, and recovery procedures.
Operations that live in people's heads rather than in documented runbooks break when those people are unavailable. Runbooks make the operational knowledge transferable, auditable, and executable by anyone on the team.
Incident response is faster and more consistent because the procedure is in place before the incident, not improvised during it.
Eliminates the operational knowledge dependency that creates risk when key team members change.
Continuous operational management across all agreed service areas, infrastructure, security, databases, pipelines, and support, with regular reporting covering system health, incident history, resolved issues, and active monitoring status.
Managed software services without reporting are invisible to the business they serve. Regular reporting keeps your team informed about what's running, what's been resolved, and what's being actively managed, so operational decisions are made with current information.
Your team retains full visibility into the operational environment without taking on the operational workload.
Reporting cadences create a structured review point that surfaces emerging issues before they become incidents.
We complete the infrastructure audit, define and agree on SLAs, set up active monitoring, and document runbooks. From day one, your operations are fully covered.
We finish the first reporting cycle, adjust monitoring thresholds based on real data, address any inherited infrastructure risks, and ensure your team has complete visibility.
Operations run according to the agreed SLAs, with performance documented. We keep your infrastructure healthy and secure, and review the operational scope to reflect any product changes made during the year.
Now that your product is live and the build phase is complete, you need a team that already understands your environment because they helped create it. They can take over operations right away, without a long handover. Shifting from a NeXus Build engagement to managed IT services is a natural next step in your partnership.
Your team is skilled, but they already handle product development, technical support, and other key tasks. By letting an IT managed service provider handle monitoring, security, databases, and pipelines, your team can focus on the work that matters most to your business.
If your current managed services provider is slow to respond, lacks transparency, or doesn't fully understand your environment, it may be time for a change. When you switch to a new provider, the process begins with an infrastructure audit. This helps everyone understand what needs attention before the transition.
We build healthcare technology solutions powered by AI to improve patient experiences and streamline care delivery and operational workflows.
We build real estate technology solutions powered by AI to accelerate lead conversion, streamline property operations, and enhance buyer and tenant experiences.
We build interactive learning apps and management systems powered by AI and data technology solutions to improve learner engagement and scale digital learning ecosystems.
We build engineering software solutions that accelerate product development, enhance R&D collaboration, and connect your product, business, and support systems using AI, IoT, and modern data platforms.
We create smart manufacturing technology solutions that provide a real-time perspective in both sales and production, supported by IoT, AI, and data technologies.
A mid-size e-commerce retailer switched to NeXus managed services three months before their busiest season. During onboarding, our infrastructure audit found a database configuration problem.
A mid-size e-commerce retailer switched to NeXus managed services three months before their busiest season. During onboarding, our infrastructure audit found a database configuration problem. The query pattern worked fine under normal traffic, but slowed significantly during peak season.
We assessed their operations and mapped use cases for AI, and discovered:
Peak trading went smoothly, with no database issues. After the season, we estimated that if the problem had happened, response times would have slowed enough to cause 23% of peak transactions to be abandoned. We found the issue four weeks before peak season, even though it had been there for eighteen months.
The query optimisation and index configuration during the onboarding period, six weeks before peak trading began.
Let us review your environment. We'll audit and document everything, then show you what managed operations coverage would look like before you decide.
Managed IT services offer proactive, ongoing monitoring, scheduled maintenance, security checks, and DevOps pipeline management. AMC, on the other hand, is reactive and focuses on fixing issues as they arise. Both support the post-build stage of the NeXus Build journey, but they meet different needs. Some clients use both, while others choose based on the complexity of their environment.