Loading service0%
Deploying and integrating AI to run reliably in your organization's infrastructure
We handle AI model deployment, connecting the built model to your live systems, deploying it on your infrastructure, and ensuring it performs under real-world conditions before it touches production.
In 6–12 months, you'll have: Agents, models, and pipelines running in production across your key workflows, integrated into the systems your teams use daily, monitored and maintained so performance holds over time.
Agents, models, and pipelines running in production across your key workflows.
The agent or model works in development. It behaves differently the moment it hits your live environment. Data formats don't match. System responses are inconsistent. What passes every test in a controlled setup fails on real inputs.
Development environments are clean by design. Production environments aren't. The gap between the two (in data consistency, system availability, and input variability) is where most AI model deployment failures originate. Nobody mapped it before go-live.
The build is done. But connecting it to your CRM, ATS, ERP, or support platform is taking longer than the build itself. Every integration surfaces a new dependency nobody accounted for in the spec.
Integration complexity is almost always underestimated because it's invisible until you're in it. Systems that look straightforward to connect have authentication requirements, rate limits, data format constraints, and availability assumptions that only surface when the connection is actually attempted.
AI implementation services start with training the model. The agent is ready. What remains is the hardest part of the technical journey: deploying it on infrastructure that must keep running. At the same time, the rollout happens, and validating that it performs under conditions no development environment can fully replicate. Four principles shape every enterprise AI implementation we run:
An agent or model that passes every test in a controlled environment is a prototype until it's been validated against real system inputs, real data variability, and real failure scenarios. We don't declare anything ready until it holds up in the environment it's actually going to run in.
AI implementation services start with training the model. The agent is ready. What remains is the hardest part of the technical journey: deploying it on infrastructure that must keep running. At the same time, the rollout happens, and validating that it performs under conditions no development environment can fully replicate. Four principles shape every enterprise AI implementation we run:
We map every system the AI needs to talk to (CRM, ATS, ERP, HRMS, and support platform) before integration work begins. Making upfront decisions on authentication requirements, data formats, rate limits, write-back logic, and what happens when a connected system is unavailable.
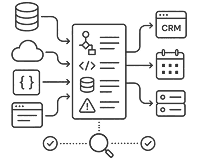
Before any build begins, we document authentication flows, data formats, write-back logic, and define behavior when a connected system returns errors. AI integration services that skip this step encounter the same issues later, at significantly higher cost.
Every AI implementation engagement follows the same technical sequence from handover to production:
(From Finished Build to Live Production)
We deliver a fully configured deployment environment (cloud or on-premise) with server setup, containerisation, access controls, and all infrastructure dependencies documented and tested before any integration work begins.
Infrastructure decisions made at go-live often create security gaps, performance bottlenecks, and long-term maintenance issues that are costly to correct later. Establishing the environment upfront creates a stable foundation for everything that follows.
The AI runs on infrastructure that meets your security, performance, and availability requirements from day one, rather than relying on post-launch remediation.
Infrastructure-related failures that commonly delay go-live by weeks are identified and resolved before integration work depends on them.
Environment configured. Integrations mapped and built. Staging validation complete. Production rollout underway at a limited scope.
Full production deployment confirmed. Monitoring active. Team operating the system without external support. First operational data coming in against performance benchmarks.
System running at full operational load. First maintenance cycle completed based on real usage. Second deployment scoped from what the first one showed in production.
After building a custom AI agent and training the model, it is time to deploy it to the live environment. What's required is the integration depth and deployment discipline to move from development to production without operational disruption. AI implementation services close that gap by handling the infrastructure setup, system integrations, and production readiness required for a stable launch.
If you have already been through a problematic go-live, you know the common causes: unmapped integrations, infrastructure that cannot handle production load, and no monitoring until something fails. Enterprise AI implementation treats deployment as an engineering process, with defined validation, staging, and monitoring, rather than as a simple handover.
Deploying a single AI agent into one system is manageable. Coordinating AI model deployment across multiple platforms, such as CRM, ATS, ERP, and support systems, introduces dependencies, integration complexity, and operational risk. AI implementation teams manage those dependencies, so integrations move together, rather than allowing a single system bottleneck to delay the entire deployment.
We build healthcare technology solutions powered by AI to improve patient experiences and streamline care delivery and operational workflows.
We build real estate technology solutions powered by AI to accelerate lead conversion, streamline property operations, and enhance buyer and tenant experiences.
We build interactive learning apps and management systems powered by AI and data technology solutions to improve learner engagement and scale digital learning ecosystems.
We build engineering software solutions that accelerate product development, enhance R&D collaboration, and connect your product, business, and support systems using AI, IoT, and modern data platforms.
We create smart manufacturing technology solutions that provide a real-time perspective in both sales and production, supported by IoT, AI, and data technologies.
An IT services and BPO firm had a sentiment analysis model built to route support calls based on the caller's frustration level. The model was trained, tested, and ready. The deployment failed because the integration between the model and the telephony platform wasn't built to handle real-time inference at call volume.
An IT services and BPO firm had a sentiment analysis model built to route support calls based on the caller's frustration level. The model was trained, tested, and ready. The deployment failed because the integration between the model and the telephony platform wasn't built to handle real-time inference at call volume.
We assessed their operations and mapped use cases for AI, and discovered:
Call transfer rates dropped from 38% to 15% within eight weeks of the corrected deployment going live: a 61% reduction. Average handle time on escalated calls fell by 4 minutes because senior agents received a transcript summary before picking up. The model hadn't changed. The deployment had.
Bring us what's been built (agent, model, pipeline, or tool) and we'll handle the integration, deployment, and go-live. No surprises mid-deployment, no integration gaps discovered after the system is live.
AI agents are the systems that get built to automate specific workflows or decisions. AI implementation is the process of deploying those agents into a live environment, integrating them with business systems, validating them under production conditions, and setting up monitoring to maintain performance.
Integrated into the systems your teams use daily.
Monitored and maintained so performance holds over time.
The agent or model works in development. It behaves differently the moment it hits your live environment. Data formats don't match. System responses are inconsistent. What passes every test in a controlled setup fails on real inputs.
The build is done. But connecting it to your CRM, ATS, ERP, or support platform is taking longer than the build itself. Every integration surfaces a new dependency nobody accounted for in the spec.
Development environments are clean by design. Production environments aren't. The gap between the two (in data consistency, system availability, and input variability) is where most AI model deployment failures originate. Nobody mapped it before go-live.
Integration complexity is almost always underestimated because it's invisible until you're in it. Systems that look straightforward to connect have authentication requirements, rate limits, data format constraints, and availability assumptions that only surface when the connection is actually attempted.
The result? Agents and models that sit finished but undeployed, or deployed into environments they weren't properly connected to, running in parallel with manual processes because the integration never fully held.
Or worse: A go-live that looks successful, followed by quiet degradation as real-world data drifts from what the system was tested against, with no monitoring in place to catch it until the business impact is already visible.
Infrastructure choices (cloud or on-premise, containerised or embedded, shared or isolated) are architectural decisions, not go-live configurations. These decisions directly affect security, latency, maintainability, and cost, which is why we make them before deployment begins, not during it.
AI models drift, data distributions change, and agents encounter inputs they were never trained on. Without defined performance thresholds and alerting, degradation stays invisible until it becomes a problem. That's why we build monitoring into the system before it goes live.
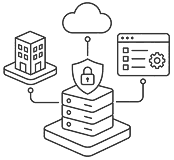
Each deployment runs entirely within your environment, cloud, or on-premise, configured to your security requirements and operated by your team after handover. There are no platform dependencies, no external services the AI relies on, and no vendor lock-in embedded in the deployment architecture.
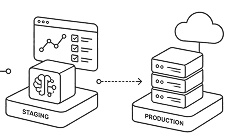
Before full rollout, the AI operates on real system inputs in a staged environment that mirrors production conditions. Edge cases, inconsistent data, high-volume traffic, and system latency are the factors that break deployments. We surface them in staging, not after go-live.
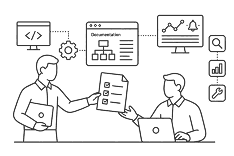
Every implementation concludes with monitoring in place, alerting configured, and documentation covering architecture, integration logic, performance thresholds, and maintenance procedures. Your team receives a system they can run confidently, not one they need to reverse-engineer.
We build and test all connections between the AI and your existing systems, with documentation covering authentication, data flows, write-back logic, error handling, and defined behavior when connected systems are unavailable.
The most common reason AI integration projects exceed timelines and budgets is that integration complexity is assumed instead of being mapped. This deliverable removes that uncertainty before a single connection is deployed.
The AI operates directly within the tools your teams already use, reliably reading from and writing to them instead of functioning as a disconnected system that requires manual intervention.
Integration failures surface during controlled build and testing phases, where they are isolated and fixable, rather than during deployment when they impact live operations.
We provide a complete record of staging validation, including inputs tested, edge cases identified, failure scenarios exercised, and formal confirmation that production readiness criteria were met.
AI model deployment to production without staging validation assumes the development environment reflects real-world conditions. It rarely does. This report serves as evidence that the system was tested against actual operational scenarios.
Leadership and technical teams gain documented assurance that the AI met required performance standards before interacting with live systems.
Issues that would have caused production incidents are detected in staging, where fixes do not disrupt operations or require rollbacks.
We execute a staged production rollout with a defined scope at each phase, performance validation before expansion, and formal sign-off once full deployment stability is confirmed.
Full-scale deployments that fail affect the entire operation. A phased rollout limits exposure, surfaces issues early, and scales only when performance is proven. Enterprise AI deployments require controlled expansion, not single-event launches.
Operations continue uninterrupted during rollout, with issues identified at a manageable scale before full-volume exposure.
Each deployment gate prevents organization-wide impact from issues that only appear at a larger scale.
We configure active performance monitoring at go-live, define alerting thresholds, and provide documentation covering deployment architecture, integration logic, retraining triggers, and operational procedures.
AI systems degrade quietly over time as data distributions shift and agents encounter inputs outside their training scope. Without monitoring, degradation is only noticed after the business impact occurs.
Your team can track performance, respond to alerts, and manage maintenance independently, without relying on the implementation team for routine operations.
Performance degradation is detected at the monitoring layer, before it affects decisions, customer interactions, or downstream systems.
The integration for real-time inference, connected sentiment outputs directly to the routing and escalation logic, and reconfigured the API calls to stay within the platform's limits during high-volume periods.